> For the complete documentation index, see [llms.txt](https://docs.glbnxt.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.glbnxt.com/tutorials/guides/openwebui/docling-in-openwebui.md).
# Using Docling in OpenWebUI
### Introduction
Docling is an advanced document parsing engine designed to convert complex, multi-format documents (such as PDFs, DOCX, and PPTX) into clean, LLM-ready Markdown or JSON structures. Integrating Docling into your n8n workflows within the GLBNXT ecosystem allows you to build highly accurate Retrieval-Augmented Generation (RAG) pipelines and document processing agents.
***
### Why use Docling?
While standard document parsers perform basic text extraction, **Docling** is specifically designed for advanced, layout-aware document processing. It outperforms OpenWebUI's default *Extraction Engine*, especially in the following categories:
* **Layout & Structure Preservation:** Docling is able to accurately identify headers, sub-headers, reading order, multi-column layouts, and list structures.
* **Complex Tables:** Standard parsers often scramble table data into disjointed lines. Docling preserves the underlying tabular grid, converting it cleanly into Markdown tables or structured JSON without losing column relationships.
* **Format Acceptability:** It seamlessly handles a wide array of file formats (PDF, DOCX, XLSX, PPTX, HTML, images) through a single extraction engine.
Integrating Docling into OpenWebUI is ideal when your RAG workflows rely heavily on complex PDFs, reports, research papers, and technical documents where maintaining original document layout, structure, and tabular integrity is critical for retrieval accuracy.
> ❗ **Note:** Converting complex or image-heavy PDFs takes noticeable processing time per page, making real-time batch ingestion slower unless optimized with GPU acceleration. For simple, single-column text files or raw `.txt`/`.md` files, Docling’s overhead is unnecessary and standard native parsers will be faster.
***
### Prerequisites
Before configuring Docling in OpenWebUI, ensure you have the following:
* **OpenWebUI Environment:** Admin access to OpenWebUI running within your secure GLBNXT workspace.
* **Docling Credentials:** Use the url provided in **Configuration** to setup your Docling Account.
***
### Configuration
#### Step 1: Configure Docling in OpenWebUI
1. Open OpenWebUI, make sure that you log in as an admin.
2. Select the Admin Account, go to Admin Panel > Settings > Documents.
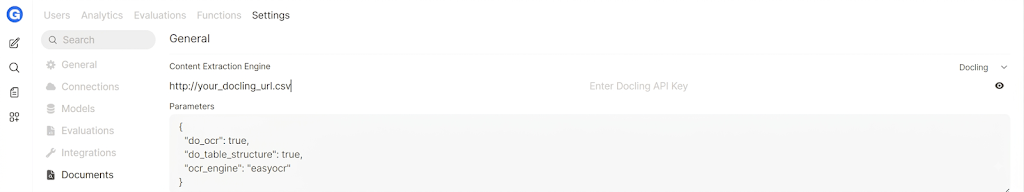
3. At the top of the page you will find "Content Extraction Engine", select from the dropdown on the right "Docling".
4. Use the **Docling Server URL:** Can be found in [GLBNXT Applications](https://platform.glbnxt.com/applications) > Services > Docling (make sure to add `.svc` after the Endpoint).
5. You can leave the **API Key** open. A detailed explanation of the "Parameters" can be found below.
6. You are now able to use Docling in n8n.
#### Step 2: Configure the Parameters for Docling in OpenWebUI
Use these parameters to customize extraction pipelines, adjust OCR models, tune table structure identification, and tweak Vision-Language Models (VLM).
To be able to use Docling in the most standard way, copy and paste the JSON body below underneath `Parameters`:
```json
{
"do_ocr": true,
"do_table_structure": true,
"ocr_engine": "easyocr"
}
```
If you would want to finetune Docling, take a look at the parameters below.
**`pdf_backend`**
* Type: string
* Allowed values: `dlparse_v1`, `dlparse_v2`, `dlparse_v4` and `pypdfium2`
* Description: PDF parsing engine
* Explanation:
\*
* **`dlparse_v1` / `dlparse_v2` / `dlparse_v4`:** Pick when parsing complex layout documents where advanced structural understanding is required (higher version numbers generally offer improved parsing models).
* **`pypdfium2`:** Pick for lightweight, high-speed text extraction from clean digital PDFs without heavy deep-learning overhead.
**`table_mode`**
* Type: string
* Allowed values: `fast` and `accurate`
* Description: Table extraction quality
* Explanation:
* **`fast`:** Pick for high-throughput processing where simple table structures need quick parsing.
* **`accurate`:** Pick for multi-page, complex, or borderless tables where precision is critical.
**`ocr_engine`**
* Type: string
* Allowed values: `tesseract`, `easyocr`, `ocrmac` and `rapidocr`
* Description: OCR library
* Explanation:
* **`tesseract`:** Pick for reliable, highly battle-tested open-source OCR supporting extensive language options.
* **`easyocr`:** Pick for deep-learning-based text recognition that performs well on difficult, noisy, or stylized images.
* **`ocrmac`:** Pick if operating on macOS system environments to leverage native Apple Vision framework hardware acceleration.
* **`rapidocr`:** Pick for efficient, lightweight CPU-friendly inference using ONNX Runtime.
**`do_ocr`**
* Type: bool
* Allowed values: `true` and `false`
* Description: Enable OCR
* Explanation:
* **`true`:** Pick when processing scanned documents, images, or PDFs that contain unselectable text.
* **`false`:** Pick when handling pure digital PDFs with accessible text streams to save processing time and resources.
**`force_ocr`**
* Type: bool
* Allowed values: `true` and `false`
* Description: Force OCR on digital PDFs
* Explanation:
* **`true`:** Pick when digital PDF text layers are corrupted, misaligned, or poorly encoded, forcing visual re-extraction.
* **`false`:** Pick to preserve native digital text streams and avoid redundant CPU-intensive image processing.
**`pipeline`**
* Type: string
* Allowed values: `standard` and `fast`
* Description: Processing complexity
* Explanation:
* **`standard`:** Pick for comprehensive processing that yields maximum extraction quality and detail across varied inputs.
* **`fast`:** Pick for high-volume jobs where throughput speed takes priority over minor quality enhancements.
**`ocr_lang`**
* Type: list\[string]
* Allowed values: ISO language codes (Tesseract: 3-letter ISO 639-2 like 'eng', 'deu', 'fra'; EasyOCR: 2-letter ISO 639-1 like 'en', 'de', 'fr')
* Description: OCR languages
* Explanation:
* **ISO 639-2 (e.g., `'eng'`) / ISO 639-1 (e.g., `'en'`):** Pick the character set codes matching the target document language based on the requirements of your selected OCR engine.
***
### Example
In the end, your (Admin Panel > Settings >) Documents page should look something like this:
 ***
*Need help? Contact the GLBNXT support team or ask a GLBNXT agent to walk you through the setup.*
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.
Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:
```
GET https://docs.glbnxt.com/tutorials/guides/openwebui/docling-in-openwebui.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.